Leaderboard VBVR-Pro-Bench, video setting · 100 tasks × 5 instances · official evaluator
Mean official-evaluator score over all 500 instances; an instance without a video counts 0. Video-model rows are the published VBVR-Pro-Bench numbers. ID/OOD is shown only for the five video models trained on the In-Domain families; for every other system the split is not a train/held-out distinction and is not reported. Click a header to sort.
| Rank | Model | Overall | ID | OOD | ||
|---|---|---|---|---|---|---|
Loading leaderboard… | ||||||
Out-of-domain vs in-domain the five benchmark-trained video models
Each row is one video model trained on the In-Domain families; the stem runs from its In-Domain score to its Out-of-Domain score. All five score lower on the held-out families than on the ones they were trained on.
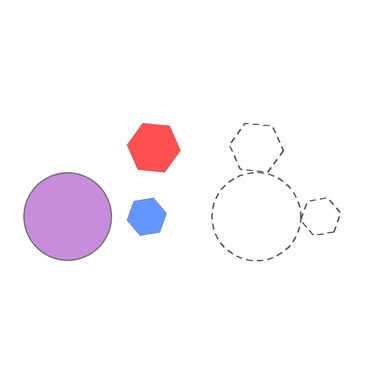
The inversion, on one task. G-24 · separate objects without spinning (out-of-domain): the agent recomputes the motion from pixels and averages 0.964 across instances; the RL-trained video model has no memory to lean on.
How a coding agent answers a video question 5,354 programs, two modes
Agents keep a constant tool fingerprint per model — Codex answers in a median of 3.2 tool calls / 22 s, Claude Code iterates with 9.2 / 105 s — and split into two ways of using their eyes.
MODE ARuntime inversion
The program itself reads the pixels: measure positions, recover parameters, then simulate forward. The code works on any instance of the task.
MODE BSession-side replay
The agent inspects the image during the session, solves the task in its head, and hard-codes the answer as constants. The code replays a decision already made.
# vision reduced to graph search — score 1.000
queue = deque([start])
parent = {start: None}
while queue:
    r, c = queue.popleft()
    if (r, c) == end: break
    for p in ((r-1,c),(r+1,c),(r,c-1),(r,c+1)):
        if p in walkable and p not in parent:
            parent[p] = (r, c)
            queue.append(p)
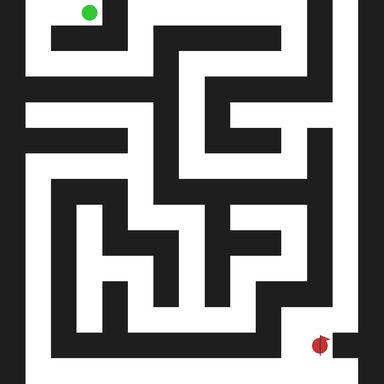
O-39 · maze (out-of-domain): the agent thresholds the walls, runs BFS, and animates the path — all three closed agents score 1.000. In spatial tasks, 39% of programs embed a search algorithm.
The medium is the win: a program can re-derive what a video model must have memorized — which is exactly why Mode A survives the domain shift and pure generation does not.
Categories & efficiency coding agents only
Per-category score for the coding agents (five VBVR-Pro-Bench categories) and how much work each agent did per instance. Cell shading: green = better score / delivery, amber = heavier workload (calls, time, tokens — neutral, not a judgment).